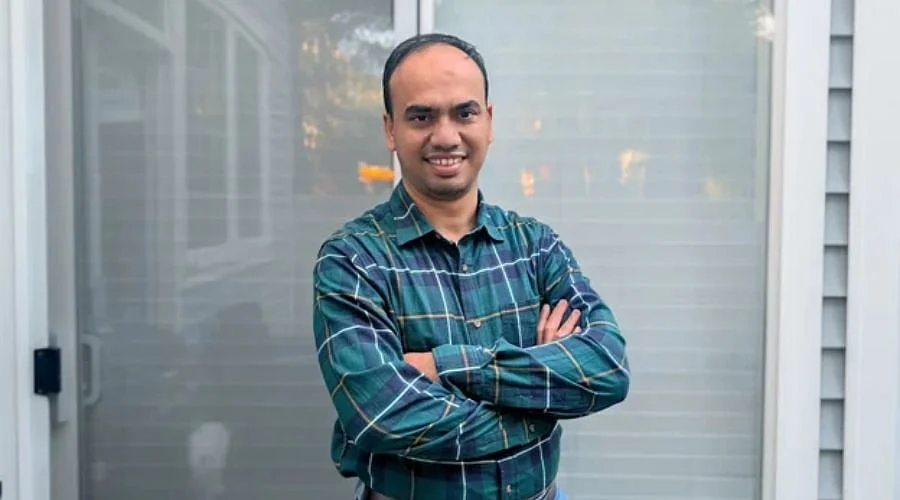
Sohail Sayed frequently returns to a single fraction: one-seventh. That represents how much search costs plummeted after his team migrated thousands of indexes spanning multiple regions to a newly rearchitected platform—all without a single customer noticing the transition, he emphasizes.
As a senior software engineer at a leading technology firm, Sayed oversees unstructured search on a platform utilized by internal product teams company-wide. When asked what most engineers misunderstand about operating at his magnitude, he replies without hesitation. “Challenges are totally different at such a scale vs a few Azure Search Services,” he points out, “but new opportunities for optimizations also open up at this scale which are not available when individual tenants host their own services.”
This perspective forms the core of his thesis, which challenges how conventional search vendors market solutions. While managing a single tenant with a single index remains manageable, Sayed deals with an entirely different tier of complexity: petabytes of information distributed across thousands of distinct customer indexes, each requiring specific data residency compliance, unique query behaviors, and zero tolerance for downtime.
The recent migration project highlights this distinction.
His group was tasked with transitioning thousands of indexes—some individually measuring multiple gigabytes—from legacy architecture to the new setup. The endeavor was constrained by two major risks: moving too quickly threatened live user traffic, while moving too slowly would drag the project out for years as incoming data continuously flooded the old system.
Success relied not on a solitary trick, but on a prioritized sequence of strategies. Sayed outlines them sequentially: temporarily boosting compute capacity specifically for the migration window, accelerating operations during off-peak customer hours, rewriting hot processing paths, staggering the migrations to prevent massive indexes from consuming all available computing cores, and meticulously tuning parallelism to level out the throughput curve.
Initial testing began on preview clusters, where the impact of any error remained isolated. This precaution proved valuable right away, exposing query throttling bottlenecks and allowing the team to devise a solid strategy before touching major geographic regions. “Issue like query throttling were identified early in preview clusters thus helping to get better plan for higher regions,” Sayed notes.
The toughest obstacles involved tenants whose data ingestion never paused. Migrating a moving target will never resolve on its own. To overcome this, Sayed’s team engineered code that brought those active migrations to what he terms a logical end, allowing the system to cut over and process the remaining data delta via standard indexing. Without this modification, some major clients would still be stuck in migration limbo.
Another perpetual challenge is the “noisy neighbor” problem. Within a shared search infrastructure, a single client generating unexpected query volume can starve adjacent tenants of resources. Sayed mitigates this proactively before provisioning. By analyzing usage patterns, high-volume tenants are identified early and assigned dedicated search services, whereas low- and medium-volume users are pooled together. Furthermore, oversight is continuous.
“Monitoring throttling and moving the noisy tenants to search services with higher resources is an ongoing process that continues post migration,” he explains. Rather than a static deployment, the network architecture remains in constant motion.
Sayed’s career path did not begin in platform engineering. He started out as a software consultant developing applications for tech companies, built an expertise in SharePoint, and co-authored a book covering SharePoint Foundation 2010. Relocating to the U.S. in 2014 as a support escalation engineer for SharePoint development, he spent five years troubleshooting production failures alongside frustrated clients. He transitioned into product engineering in 2019, eventually leading to his current role.
This background heavily influences his stance on tenant isolation. Having spent years fielding emergency calls from troubled customers, he treats service disruption as an outcome to be prevented at nearly all costs, even when it complicates the underlying engineering.
Compliance requirements introduce further complexity. Regional data residency laws and mandatory tenant isolation are non-negotiable, and the platform must maintain reliability at a scale where even a tiny percentage of failures translates to a massive volume of disgruntled users. Rather than viewing these as mere constraints, Sayed sees them as the very drivers of innovation. Managing the underlying substrate for thousands of tenants unlocks data partitioning methods entirely unavailable to single-tenant deployments.
While the 75% cost reduction serves as the standout metric, Sayed emphasizes that performance and dependability advanced in tandem. This progress stems from the team’s newfound ability to direct compute power precisely where required, instead of relying on legacy provisioning from years past.
He continues to shift tenants across the system—a task he notes is simply part of the job description that never truly concludes.